Field notes: the renewal where one new feature finally told two look-alike risks apart
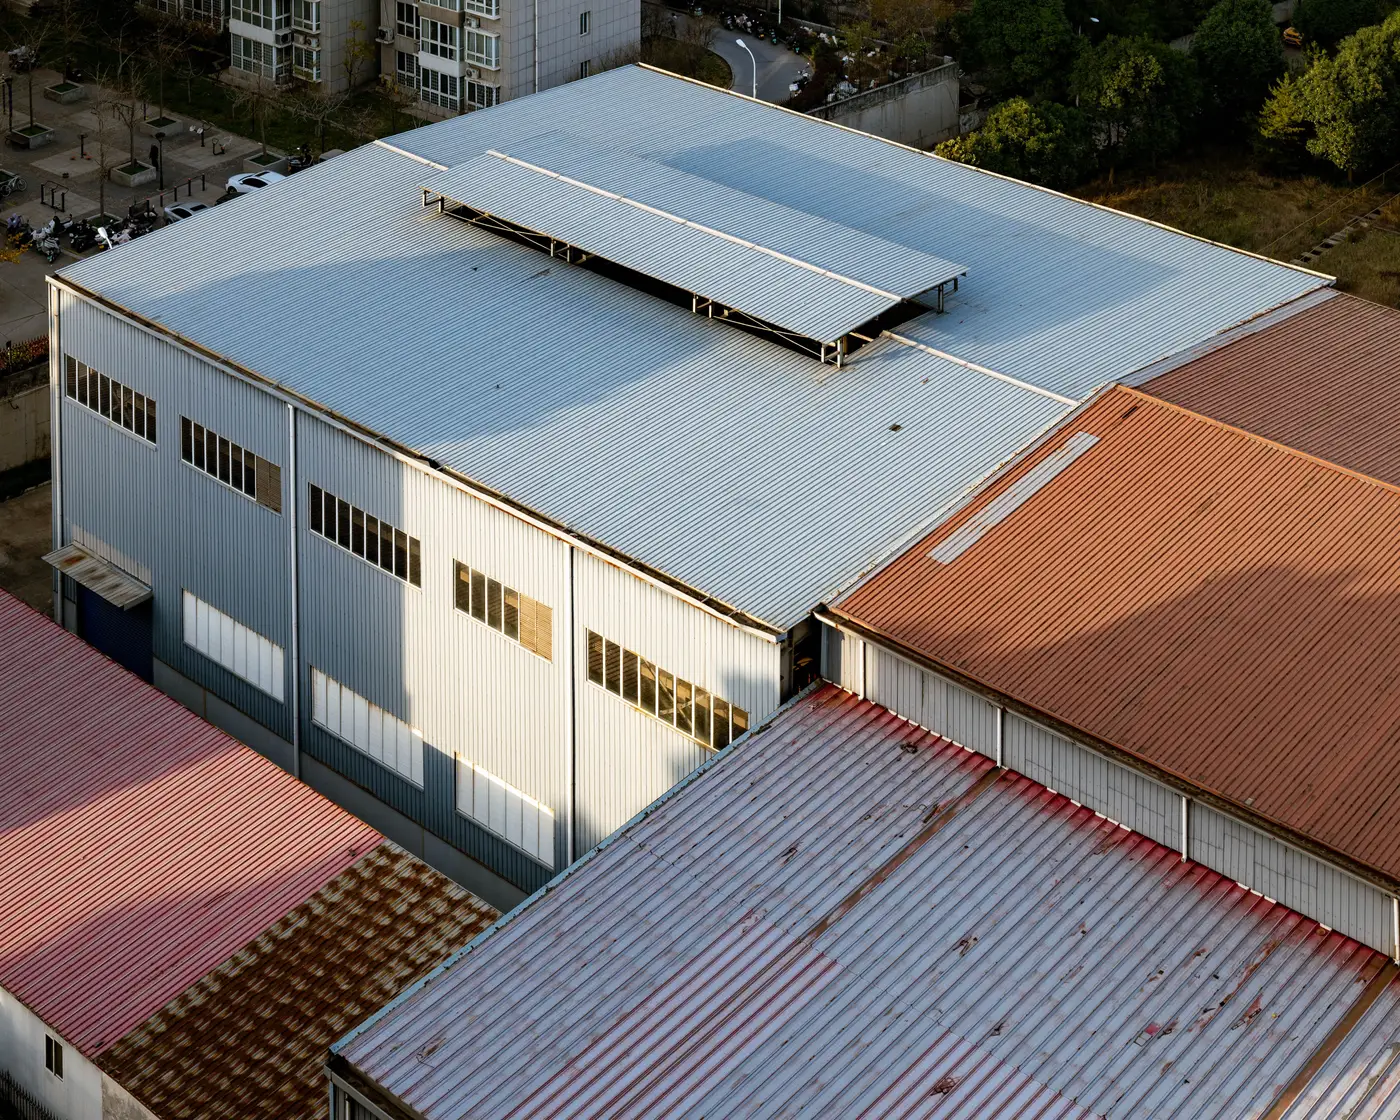
Every book has a pair like this somewhere. Two sites, same occupancy code, same construction class on the schedule of values, same TIV band, built four years apart in neighboring counties. On paper they're the same risk. The rating engine treated them that way for three renewals running, and nobody flagged it because there was nothing to flag. The bordereau doesn't lie, it just doesn't say enough.
This year it caught up with us. One of the two sites had a loss, a roof-cover event that ran well past what the occupancy code and construction class would have predicted. The other sat clean. Same inputs, different outcome, and the usual answer, "the model has error bars," stopped being satisfying once the loss ran through the layer twice.
So we went looking for what the schedule couldn't tell us. Pulled up both addresses in plain aerial imagery first, nothing fancy, just to see what we were underwriting. The difference was obvious in about four seconds.
The site that lost had a built-up roof with visible ponding and a cluster of rooftop units bunched on one half, the kind of load distribution that shows up as a weak point once wind gets under an edge. The clean site had a newer membrane roof, tidier equipment layout, better drainage lines. Same construction class code. Completely different roof.
That's the thing about occupancy and construction codes on a bordereau: they describe a category, not a building. A reinsurer scoring a cedent's book at renewal is stuck rating the category, because going site-by-site on five thousand locations with an engineer isn't a renewal workflow, it's a consulting engagement nobody's budgeted for.
What changed this cycle wasn't that we hired someone to eyeball every roof. We ran the whole site list, the lossy pair included, through an embedding model trained on imagery rather than on a fixed attribute list. No roof-condition field to define in advance, no tagging exercise to brief an analyst team on. Just a vector per site that encodes whatever the imagery shows: rooflines, surrounding density, vegetation, drainage patterns, the stuff that never makes it onto a SOV because nobody thought to ask for it as a line item.
Dropped that vector into the scoring model as an additional feature, alongside the usual rating variables, and re-ran the pair. They separated. Not dramatically, not a hard rule that says "flag this roof," but enough distance in the score that the model stopped treating them as interchangeable. We've since run it across the rest of the book in that peril zone and found four more pairs with the same pattern: identical on the schedule, meaningfully different in the imagery, and in two cases a loss history that had been quietly inflating the attritional assumption for a whole construction class because of what turned out to be two or three outlier buildings dragging the average.
None of this replaces engineering inspection where the limit justifies it. What it does is give the scoring model something between "trust the occupancy code" and "commission a site visit," which for a renewal with a two-week turnaround is most of the gap that matters. We didn't define what the feature should capture ahead of time. That's the part that took getting used to. You stop writing a spec for the signal and start checking whether the model found one worth having.
If your book has pairs like this sitting in it right now and you don't know it yet, the quickest way to find out is to see what an imagery-derived feature does to your own scoring model before the next renewal cycle locks in, which is the whole reason the vectors on the Imagery Embeddings site are built to drop straight into a model you already run, not replace it.
Worth a look before the next treaty crosses your desk.